
Amazon Web Services (AWS) has detailed its "Project Rainier" supercluster of Trainium2 chips in a blog post.
First announced during the Re:Invent event in Las Vegas late last year, Project Rainier is being developed alongside generative AI company Anthropic and will be a cluster of Trainium2 UltraServers containing "hundreds of thousands" of Trainium2 chips interconnected with third-generation, low-latency petabit-scale EFA networking.
Podcast Episode Bonus episode - Understanding AWS' chip strategy with Gadi Hutt
The cluster will be spread across multiple data centers in the US and will be used by Anthropic to build and deploy future versions of its AI model, Claude. Only one of the data center locations - St. Joseph County, Indiana - was listed by name.
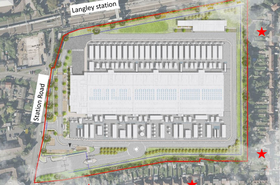
AWS announced plans for a St. Joseph County campus in April 2024 - committing to investing $11bn in the site, and breaking ground in October 2024. Images have suggested the campus could feature up to 22 buildings.
The blog post adds that the new data centers being constructed for Project Rainier (and beyond) will include several upgrades for energy efficiency and sustainability, and will minimize water use.
“Rainier will provide five times more computing power compared to Anthropic’s current largest training cluster,” said Gadi Hutt, director of product and customer engineering at Annapurna Labs. "For a frontier model like Claude, the more compute you put into training it, the smarter and more accurate it will be. We’re building computational power at a scale that’s never been seen before, and we’re doing it with unprecedented speed and agility.”
Project Rainier is described as a massive “EC2 UltraCluster of Trainium2 UltraServers.” The UltraServers, also launched by AWS last year, have 64 Trainium2 chips and can offer up to 83.2 FP8 petaflops of compute power and are effectively four instances combined into one node and communicated via high-speed connections called "NeuronLinks." Each UltraServer is then connected by Elastic Fabric Adaptor (EFA) networking technology, inside and across data centers.
The blog post adds: "When you connect tens of thousands of these UltraServers and point them all at the same problem, you get Project Rainier—a mega “UltraCluster.”
The exact number of UltraServers to be deployed under Project Rainier is unclear, but AWS has previously said it will eventually have hundreds of thousands of Tranium2 chips.
The Trainium2 chips use a systolic array architecture. Hutt previously told DCD: "Basically, data flows through the logic of the systolic array that then does the efficient linear algebra acceleration," explaining that the chips are not able to handle the same variety of problems that GPUs might: "These chips are designed to do linear algebra, accelerate linear algebra, and pace in high utilization.”
Oracle Cloud Infrastructure similarly has been constructing what it calls "Superclusters," though using third-party hardware.
Earlier this month, Oracle announced plans for an AI cluster with up to 131,072 of AMD's new MI355X GPUs.
The company also has an Nvidia GB200 NVL72 OCI Supercluster with 131,072 Blackwell GPUs, and Superclusters of the H100 and H200 GPUs.




Comments