

Hyperscalers built their empires by innovating to make other people’s infrastructure obsolete. But there’s a fundamental difference between innovating to expand and grow, and innovating just for the sake of it.
The recent reveal of JBOK, Amazon Web Services' (AWS) attempt to use its own custom network cards alongside Nvidia’s latest rack-scale system, may have found itself in the latter category.
The casus belli behind the creation was simple: Nvidia’s NVL72 rack-scale system uses shorter 1U server trays, leaving AWS unable to physically fit its own network cards into the trays.
The solution? Add a separate cabinet just off to the side that’s full of just network cards.
Think Wallace & Gromit’s motorcycle, but Gromit is a server rack and Wallace is a K2v6 network interface card (there’s no official image of what AWS’ custom NIC looks like, so just use your imagination). One processes all the information, the other does the steering, all while operating in tandem … and much to this writer’s dismay, with a lot less cheese involved.
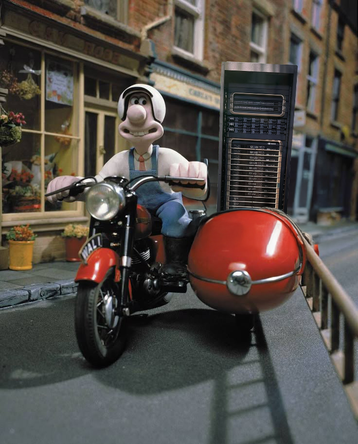
Just a bit of harmless software optimization, that's all
While hyperscalers like AWS are racing to perfect proprietary hardware, every engineer-hour spent on projects like JBOK is an hour not spent on what actually differentiates them from the other cloud providers left in their dust: the software layer.
Instead of pouring time staring at JBOK cabling diagrams, this is where the real improvements can be made.
Take the results from the recent InferenceMAX v1 benchmark. Here, Nvidia’s NVL72 system came out on top on metrics like throughput-per-dollar and tokens-per-megawatt, with software innovations helping to push performance levels. The addition of routinely updated inference frameworks like TensorRT-LLM and Dynamo helped to bring down cost levels for running intensive AI models when compared to rival systems, like AMD’s MI355X.
At the inference level, software additions like the recently unveiled Grove – which AWS is using to accelerate inference for customers running AI workloads via its Elastic Kubernetes Service (EKS) – help push the needle on performance, not the addition of newer hardware.
And yet, in the case of JBOK, AWS diverted world-class engineering talent to solve a problem of its own making.
According to SemiAnalysis, the company's previous workaround, NVL36x2, resulted in more bugs than using Nvidia's native NVL72 design. That's not just wasted engineering hours on the initial design; it's accumulated technical debt that requires ongoing maintenance, debugging, and customer support.
That’s not to say AWS doesn’t have its engineers working on optimization projects, of course. But when examples like researchers from Perplexity find that Amazon’s EFA requires larger messages to saturate, which impacts performance, the hyperscaler’s conviction is costing engineering bandwidth that could be spent proving it through software performance, not elaborate workarounds.
The irony is particularly sharp when you consider AWS' market position. The hyperscaler didn't build its cloud empire by obsessing over physical infrastructure elegance; it won by making infrastructure invisible to customers through brilliant software abstractions. EC2, S3, Lambda: these were services that succeeded because they hid complexity, not because they added it.
Every hour spent on JBOK is an hour not spent on the innovations customers actually want to see, like reducing cold start times for inference endpoints, or building better cost estimation tools for multimodel deployments.
For all the engineering effort behind it, what with a punny name and a whole extra cabinet just to maintain control and avoid vendor dependency, it’s hard not to see the funny side of JBOK. In trying to avoid being locked into Nvidia's “subpar” ecosystem, AWS has locked itself into the architectural complexity of its own making.



Comments